One of the key questions when building a new AI model is how good the model is for the target customer. It is also for the AI users: how good this model is for my use case. When it comes to Text To Speech (TTS), many of us want to know how existing TTS models work best for my particular language. To answer this question, Podonos have been working hard to evaluate multiple AI models for TTS along multiple dimensions including language, evaluation types (naturalness, quality, intelligibility, preferences, and many more) As the first step, we would like to release evaluation results of OpenAI's TTS model for Korean.
How naturally does OpenAI's Text To Speech speak Korean?
We have observed amazing performances of models released by OpenAI (ChatGPT, o1, DALLE 3, SORA) Their breakthrough voice conversational skills have impressed many of us. The core question is how natural their TTS model is for each language, especially non-English languages as we expect they have great job done in US English. As a side note, we are actively evaluating and comparing multiple text to speech models across multiple languages. So, let's take a look.
Evaluation Setup
For the evaluation of OpenAI's TTS model for Korean, we use a randomly selected test set from KsponSpeech dataset, which is widely used dataset for training and testing voice AI models. Among them, we use the test set, which is not typically used for training AI models.
We generated the speech out using the OpenAI's TTS model, used Podonos evaluation for naturalness from real human, who speaks Korean as their first languages and currently live in Korea. So the human evaluators are the best for this evaluation. Of course, our system automatically validates evaluators by checking their audio devices, hearing capabilities, general intelligence, and the attention span. And the evaluation scale is 5=excellent, 4=good, 3=fair, 2=poor, 1=bad. So the higher score, the better the model is.
Ok, Tada! Here is a link to the evaluation report.
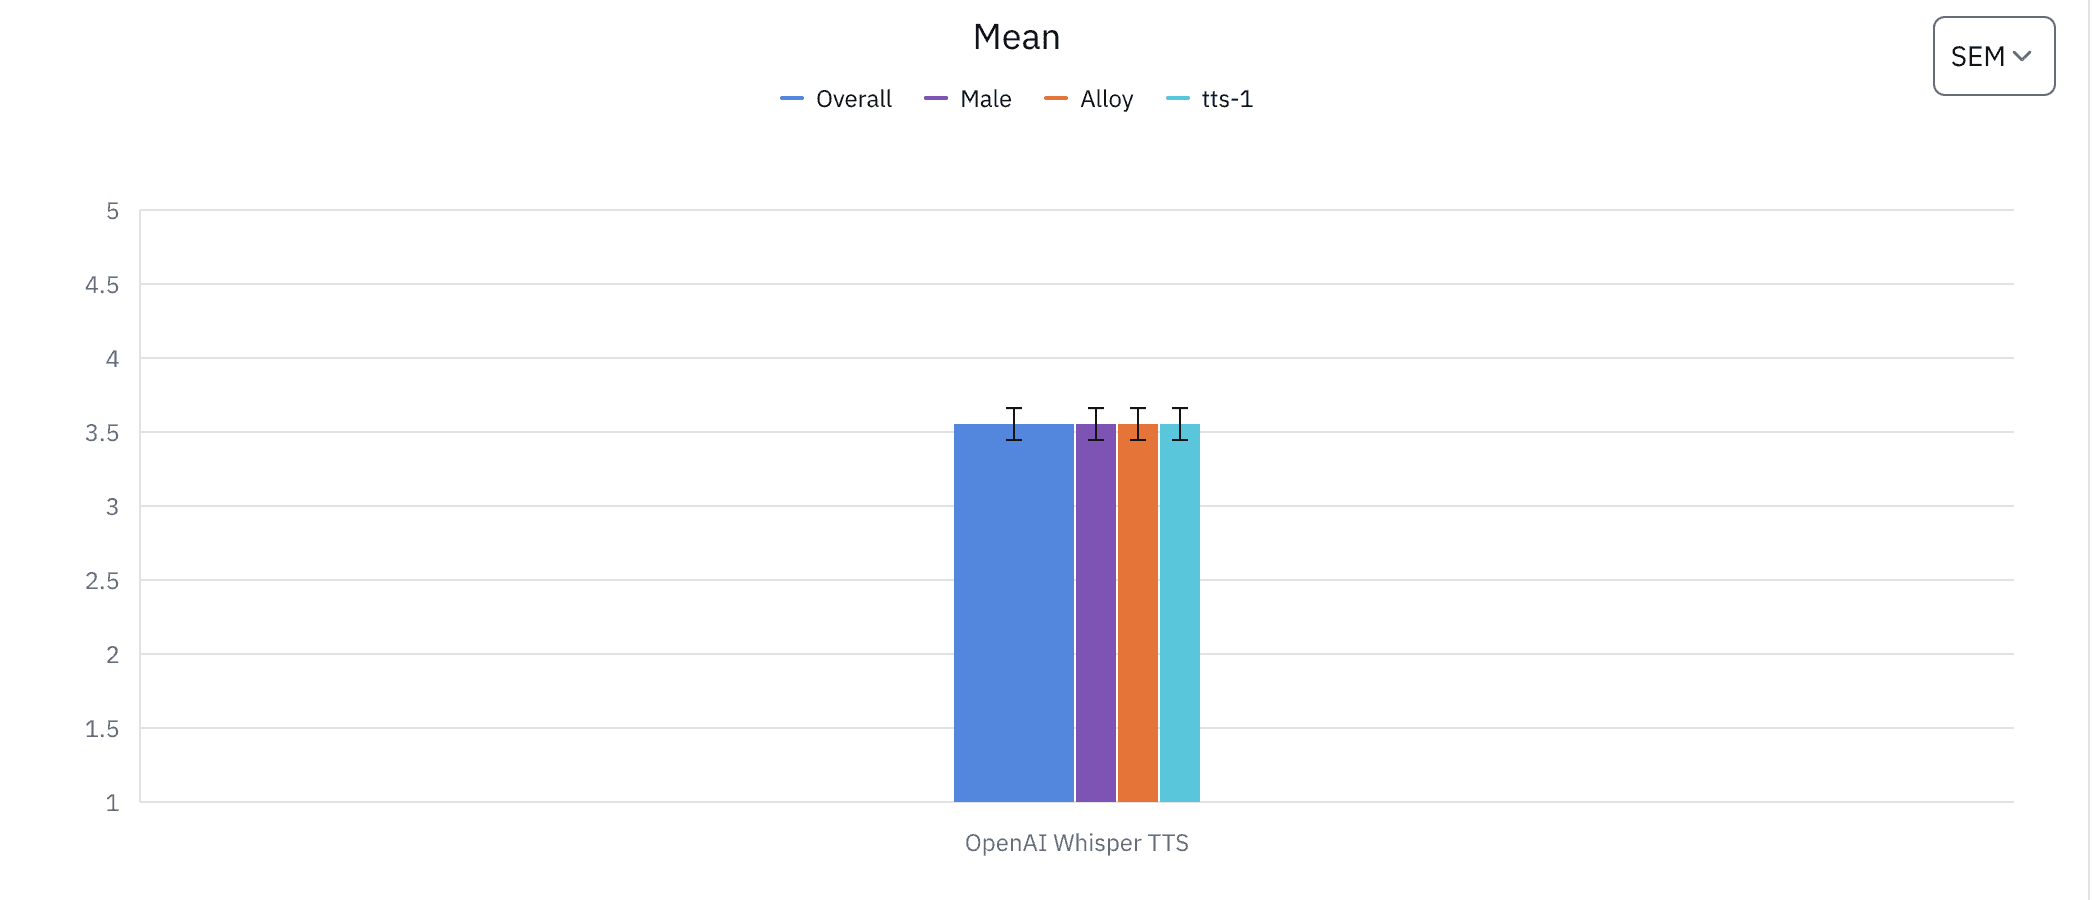
You can see the overall naturalness score is **3.55**, which is **between good and fair**. You see the error bar, which is the standard error of mean, used for measuring the statistical significance. It is **0.11**, fairly small, so the overall score is trustworthy. Also, you can switch "SEM" to CI95 (Confidence Interval 95%) or Std (Standard deviation) to see other significance measures.
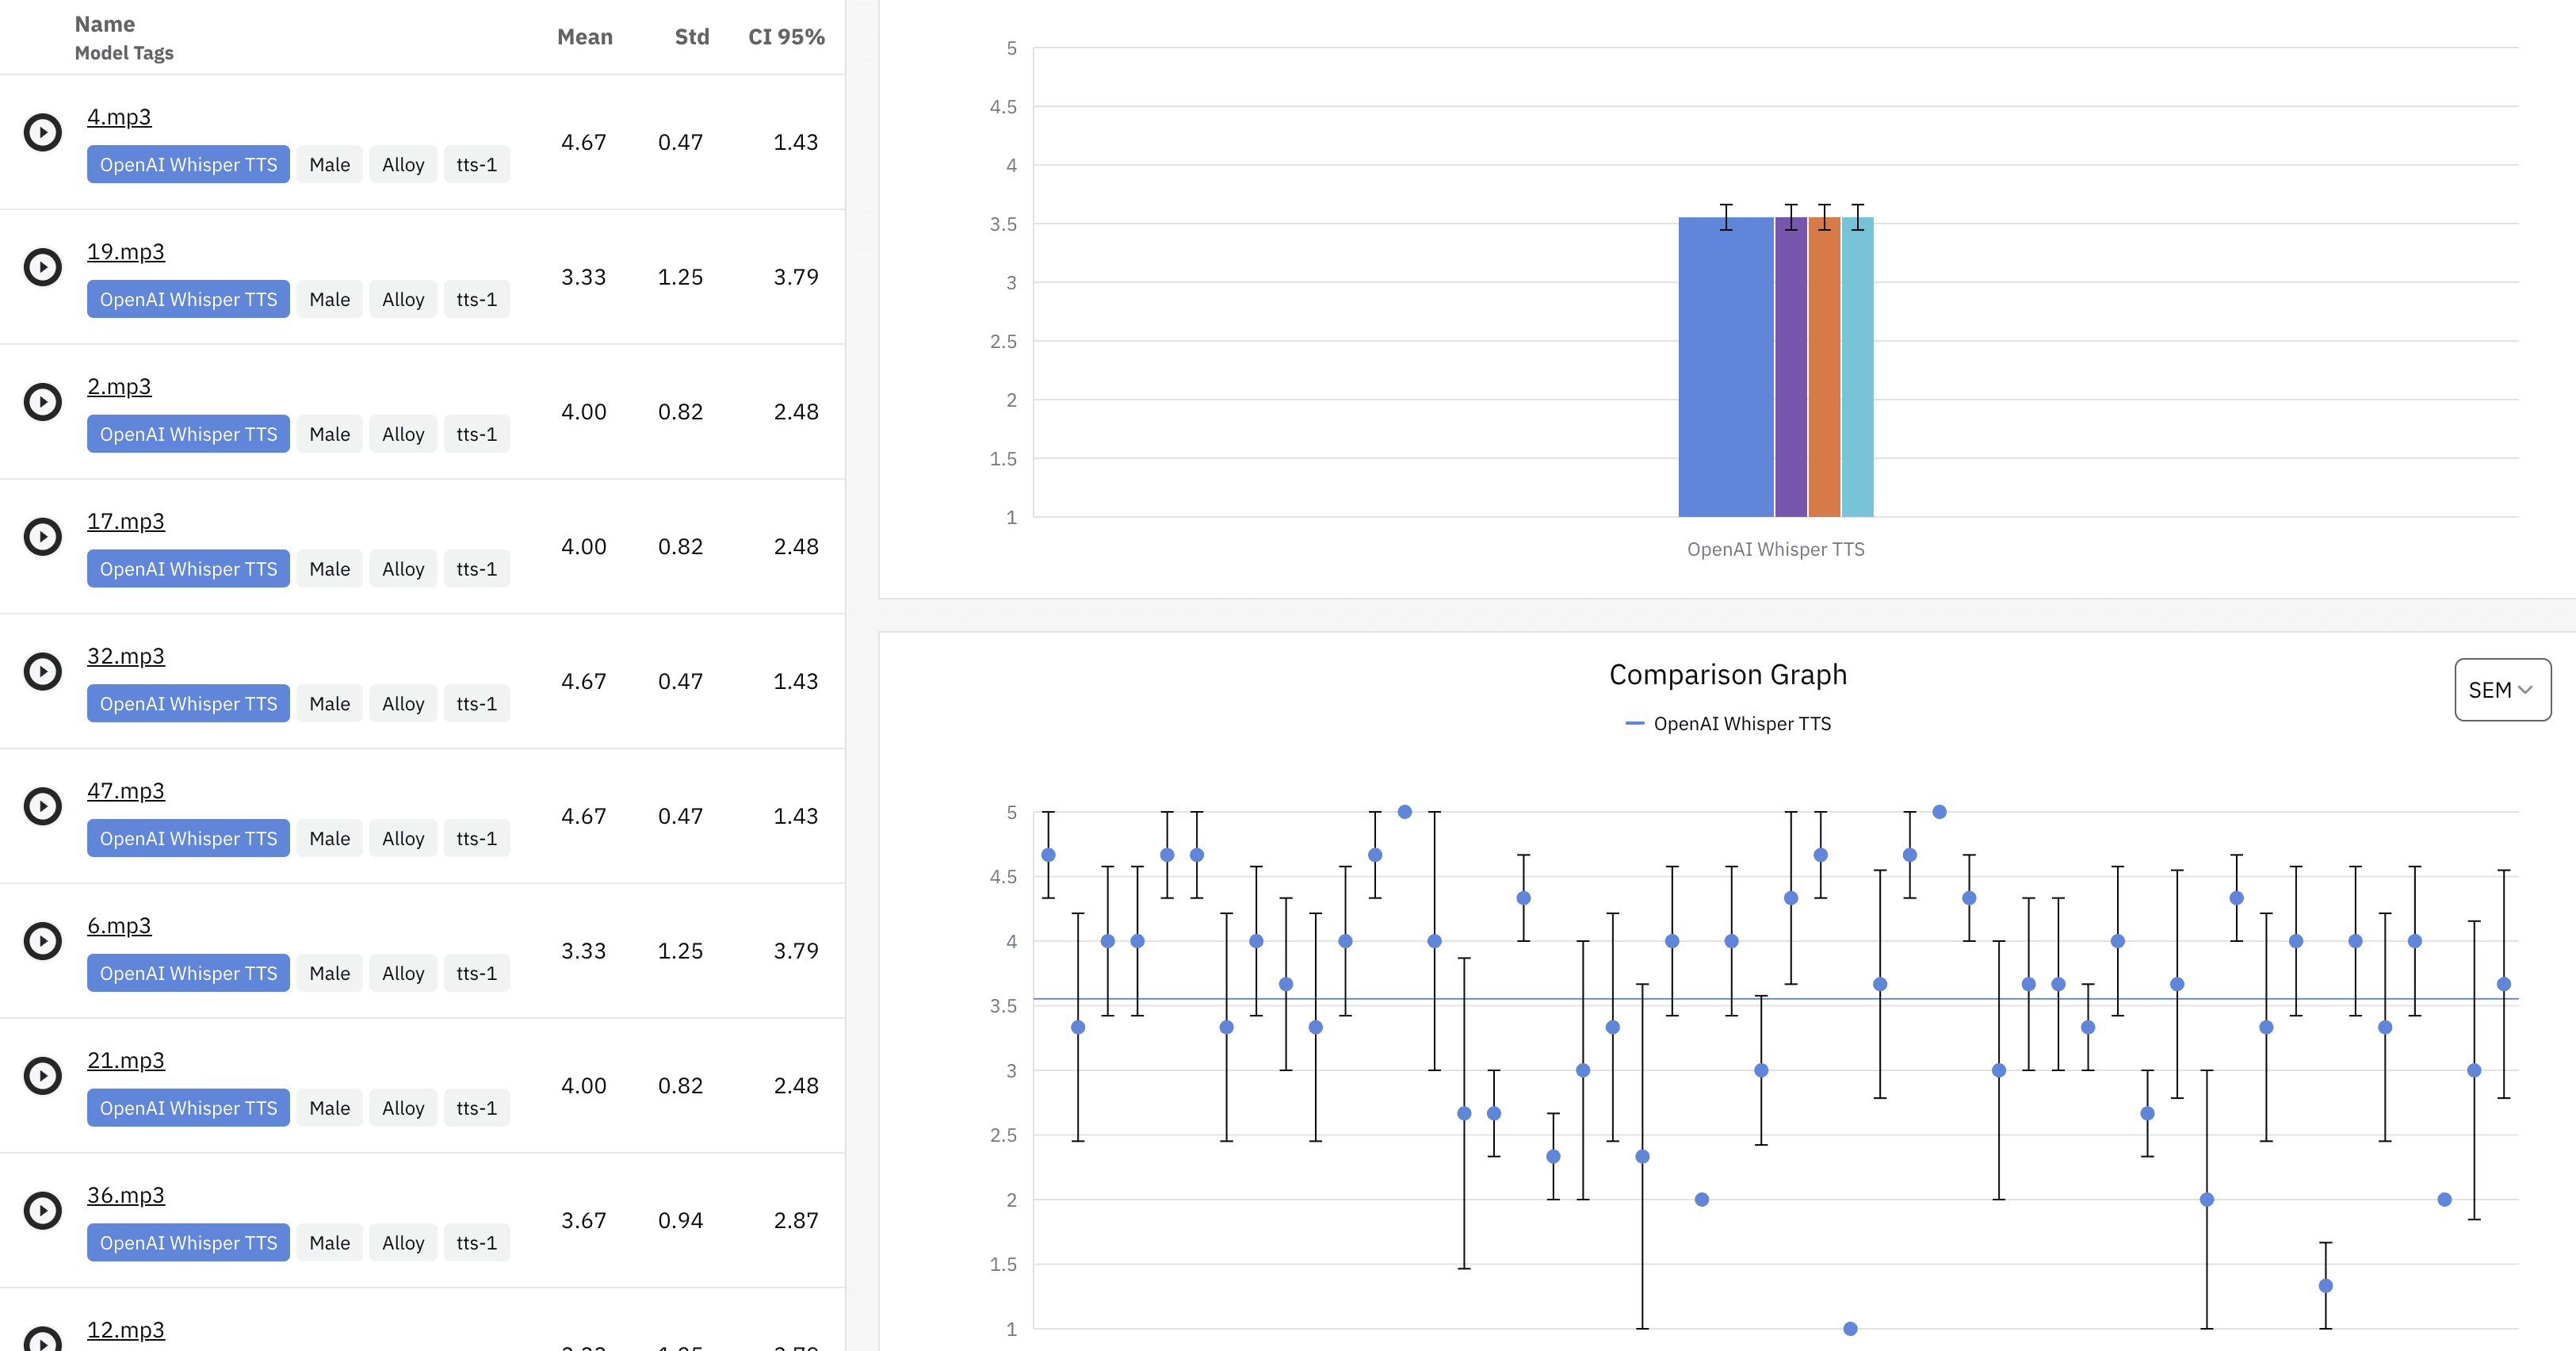
As a next step, let's take a look at the naturalness scores of individual test audio files.
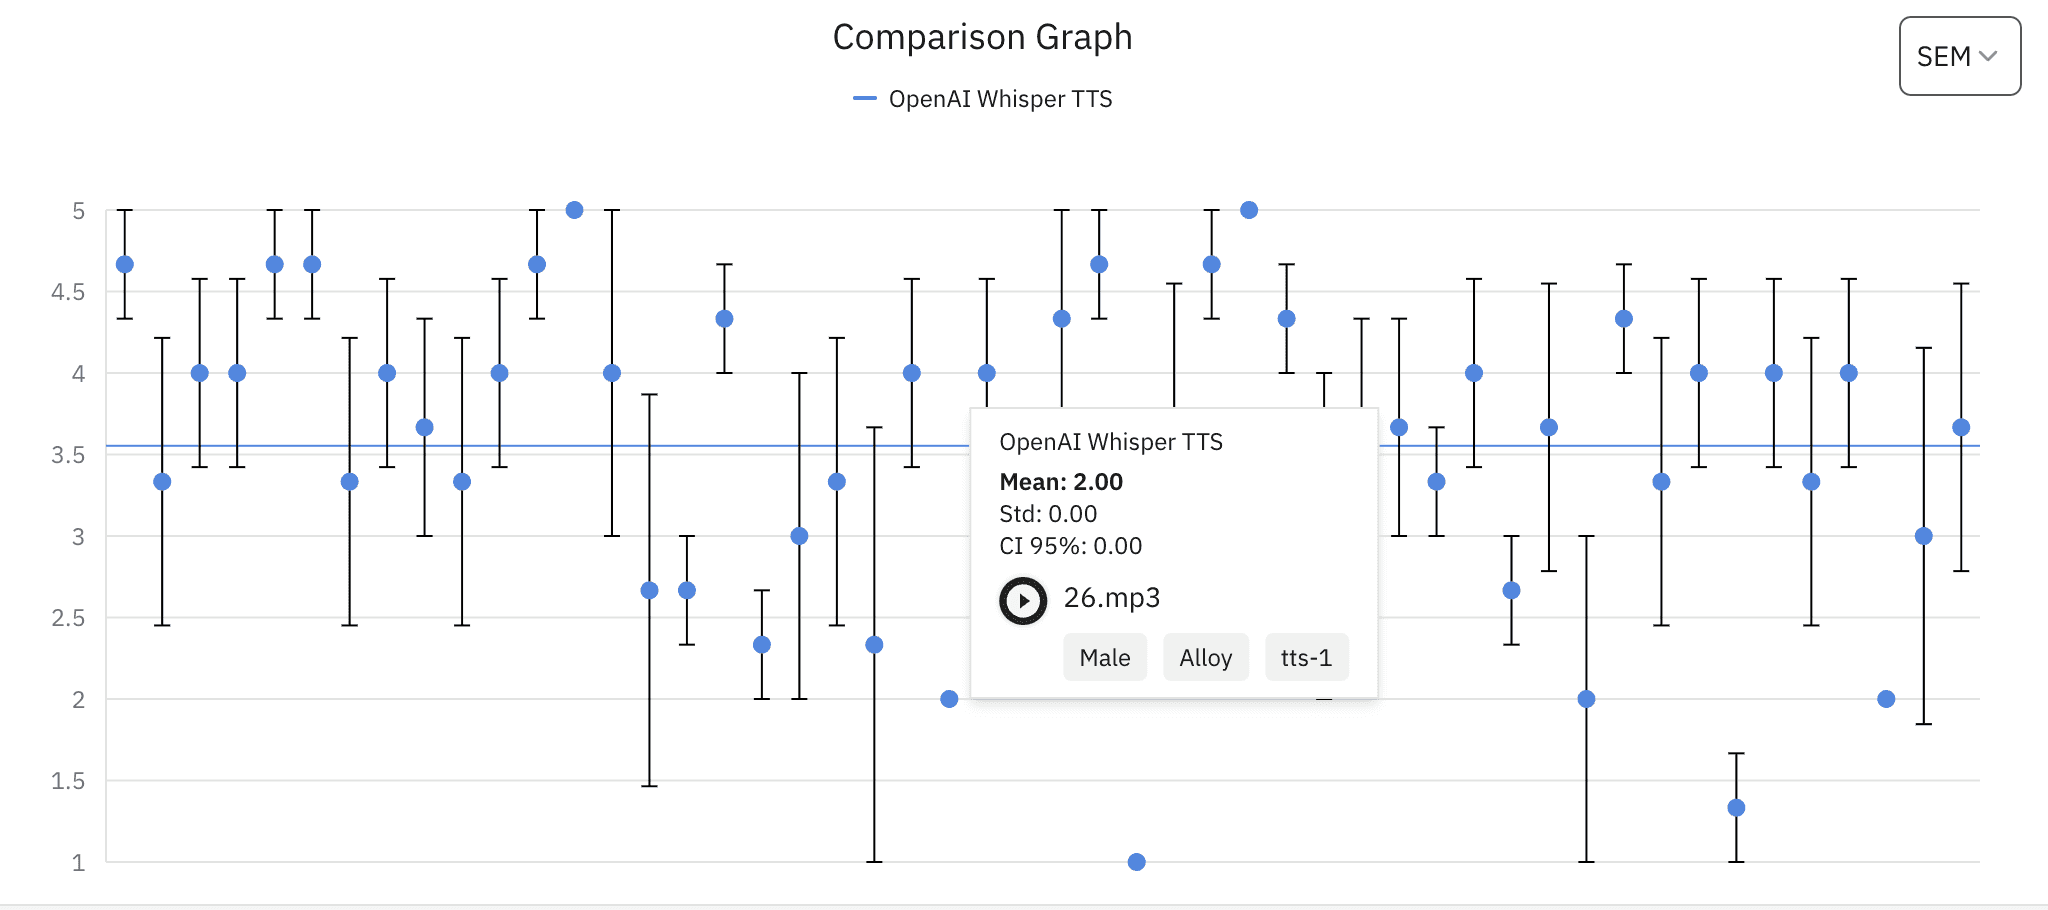
Each dot corresponds to each synthesized output. You may want to take a look at those in low scores. Then, click, now you can see the individual statistics and play the audio file. The figure above shows an example of one file with statistics.
As we go deeper, you may wonder why the human evaluators think some samples are good, some others are bad. At the top-left corner, you see the "Files" button, open it. You see the whole list of files, the tags, and the scores. Click the file name. Then, you can see the script used for generating the output.
One amazing feature is the annotation of the particularly good or bad results. In this case, the evaluator marked "25" and put reasons "스물다섯명 발음이 매우 어색함", which is translated to "the pronunciation of 25 is very unnatural".
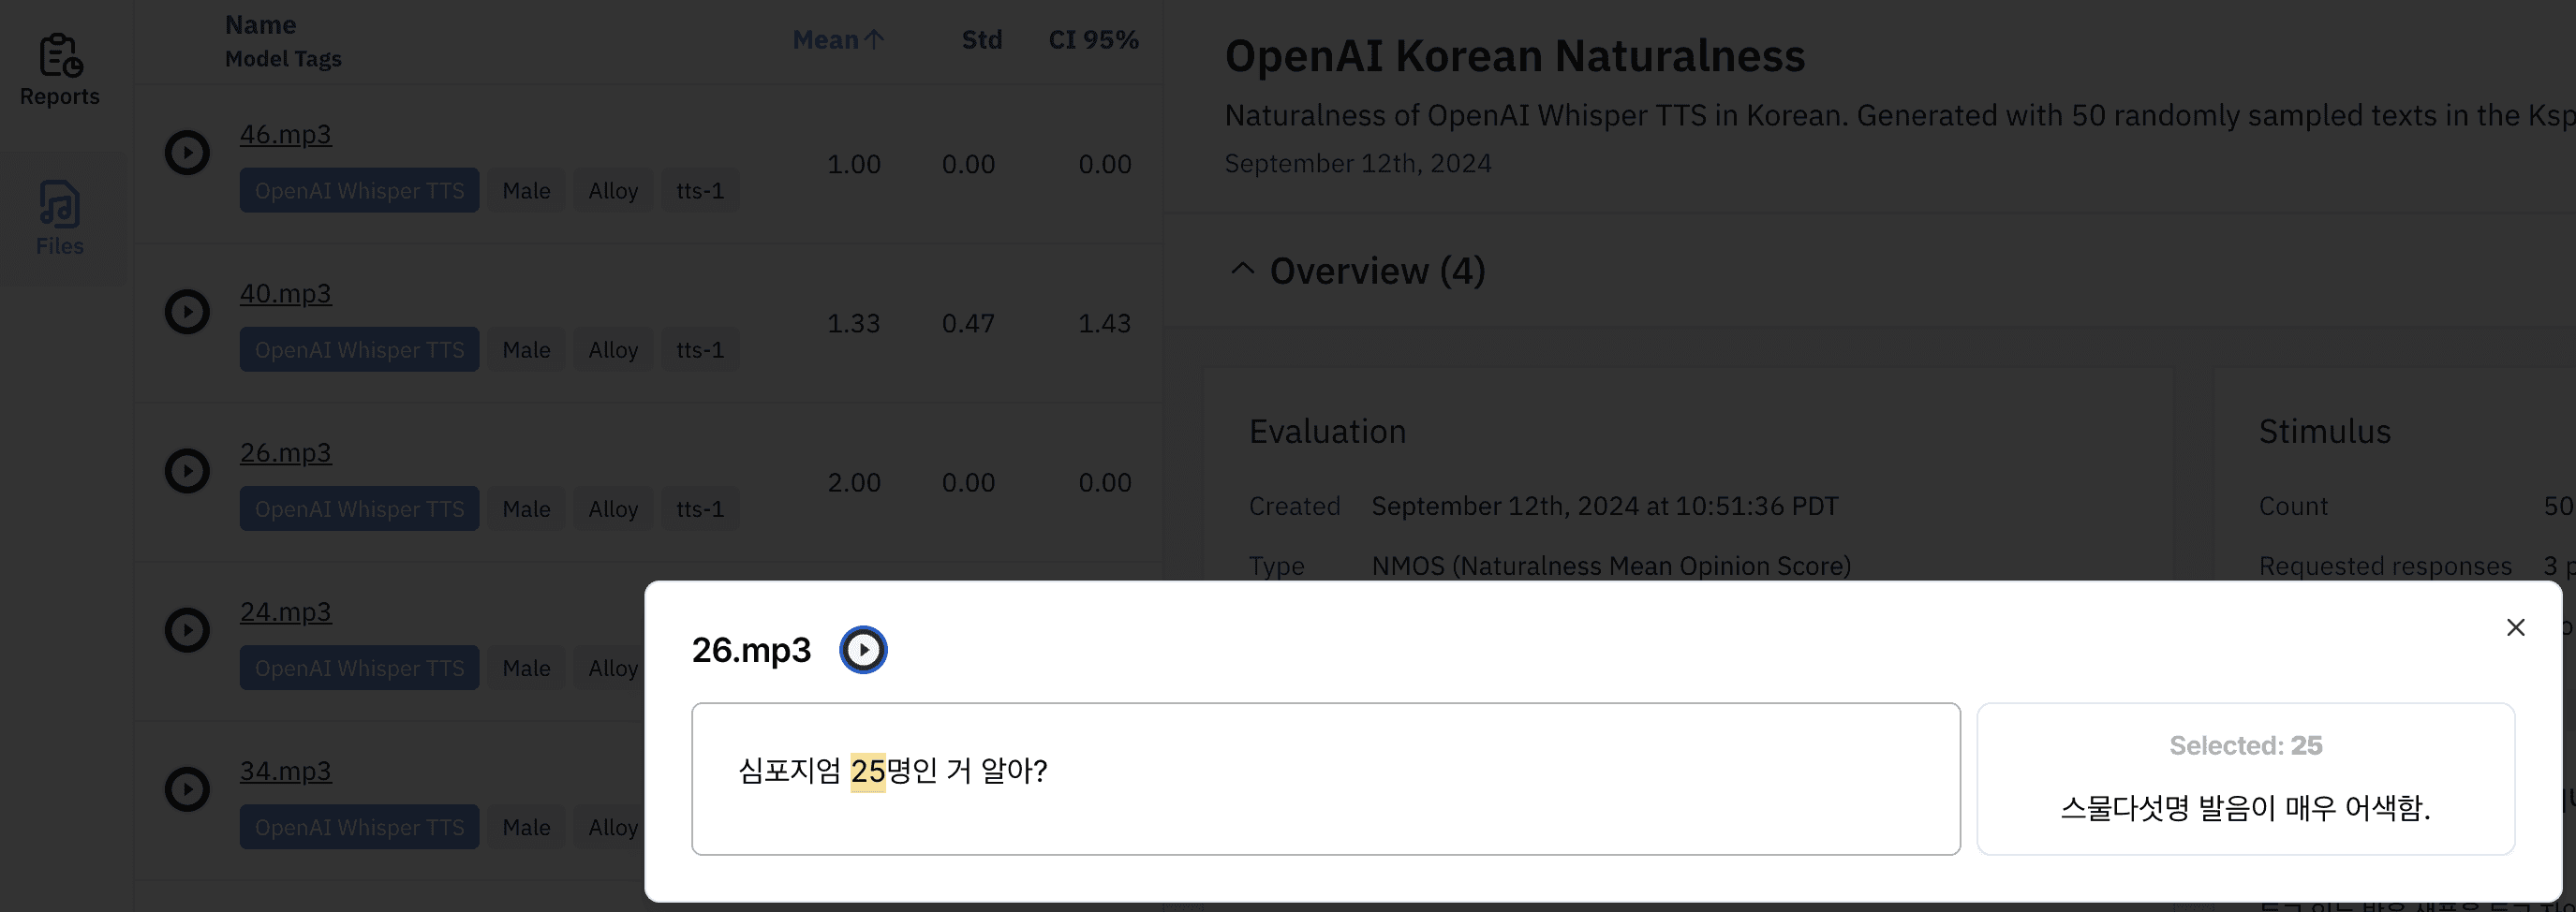
The great value of this annotation is that these dataset can be used for further finetuning the model, so called post-training data. After training a model or accessing a pretrained model, you can further improve it toward your use case. You can access the data by this SDK API.
We will release more results of other TTS models across different languages on multiple evaluation types. Stay tuned!